Thursday, November 19, 2026


DIGITAL LIFE


Why the first ai "did not take gender equality into account at all"...

The first wave of artificial intelligence (AI) "did not take gender equality into account at all" and "not only discriminated but also amplified discrimination," an expert observed at the Gender Equality Forum, which concluded today in Brussels.

The first wave of artificial intelligence (AI) "did not take gender equality into account at all" and "not only discriminated but also amplified discrimination," an expert noted at the Gender Equality Forum in Brussels.

Speaking via video conference at the event—organized by the European Institute for Gender Equality (EIGE), a European Union agency based in Vilnius, Lithuania—Alessandra Sala noted in a subsequent interview with Lusa that some companies are now adopting a more careful approach, treating gender equality and diversity as variables to be considered.

However, the researcher and AI scientist—a vocal advocate for responsible and inclusive AI—pointed out that "fundamental problems still exist," both among developers and providers.

"We are investing heavily in creating intelligent systems, yet these systems are not being built with care or with gender equality principles in mind," she stated. She urged entities that provide AI services or products to do more, emphasizing that "it is their responsibility to continue refining" these tools, ensuring adherence to "principles of safety and transparency, while mitigating bias and discrimination."

An inclusive AI is one that "guarantees equal opportunities, regardless of gender, social class, or cultural or religious differences," she explained, adding: "All individuals [as users] have the right to receive the same quality of search results."

To achieve this, "the model must be built with an inclusive perspective, taking into account the risk of bias and discrimination," she suggests. EIGE brought together several dozen experts in the Belgian capital to reflect on gender equality and the challenges surrounding it.

Concluding the meeting, Hadja Lahbib, the European Commissioner for Equality, noted that women continue to perform six weeks more of unpaid work than men—a gap that has narrowed by "only a day or so."

In 2026, starting on November 20th, women will effectively be working for free for the remainder of the year—a disparity that, at the current pace, will persist for decades to come.

Regarding the Gender Equality Index unveiled today—which places the EU at 64.5 points (out of 100), an increase of just 0.9 points since last year—the Commissioner remarked that "all Member States have made progress, but too slowly, and even more slowly since 2020."

At the same time, "some have regressed," she pointed out, adding: "The index tells the truth, even when it hurts—and it does hurt."

According to EIGE estimates, at this rate, it will take at least two generations for the EU to achieve full gender equality.

In this year's index—a tool used to measure gender equality within the EU—Sweden has lost the top spot to France for the first time since 2013.

Portugal ranks 9th and was the country that showed the fourth-greatest improvement.

Cyprus, Hungary, and Czechia recorded the lowest performance in terms of equality.

AI experts called on researchers and institutions to look more deeply and critically at the foundations of the technology and its impacts on people and resources, in a recent Clayman Conversations event, “Gender, Power, and Artificial Intelligence.” Even further, the panelists said, it is important to question the environments that allow the unchecked growth of AI to flourish and consume, and to exacerbate gender, race, and class inequalities. 

The panel included Safiya Noble, the David O. Sears Presidential Endowed Chair of Social Sciences and professor at UCLA, where she is the director of the Center on Resilience & Digital Justice and co-director of the Minderoo Initiative on Tech & Power; Catherine D’Ignazio, an associate professor of urban science and planning at MIT, where she is the director of the Data + Feminism Lab; and Angèle Christin, associate professor of communication, HAI senior fellow, and former Clayman Institute faculty research fellow at Stanford University. The event was organized and moderated by Clayman Institute Postdoctoral Fellow Genevieve Smith.

“There’s a certain sameness in terms of this gold rush mentality,” D'Ignazio said, through the previous business and technology development cycles of big data, algorithms, and now on to AI and generative AI. She worries more about the consequences when compared with those previous development cycles, noting the current scale of ambition, extraction, and technical architecture cannot be sustained.

“The feminist project at its core addresses unevenly distributed power,” D’Ignazio said. “The current AI moment represents an acute intensification of resources and power,” particularly in terms of the land, water, and energy – as well as massive amounts of capital – required for data farms. She noted, “We might actually be able to accomplish a lot of these tasks without such a compute-intensive, land-intensive, water-intensive, energy-intensive architecture,” but those important conversations are not happening.

Noble, author of the groundbreaking book Algorithms of Oppression, turned to Black feminism and transnational feminism frameworks to help contextualize the larger costs of these choices, both in terms of extraction and waste and in the effects of the technologies themselves on users. The resource issue is a global challenge, she said, including the global manufacturing supply chain and mineral extraction in places such as the Congo or Australia. While AI is particularly helpful for coding, she said, people who code – mostly men – have an overinflated view of its usefulness. Beyond that realm, “What is the point of any of it?” she asked. “What is it costing us in cognitive and social effects?” Referencing technology’s impact on young people and digital dementia in older users, she said, “Every generation is addicted to technology.” This inevitable march of adoption and so-called progress, Noble said, precludes accountability, justice, and repair from AI’s harms.

D’Ignazio called out the biases inherent in AI data, noting that data is not necessarily true or comprehensive, but full of flaws and inconsistencies. Studies have shown that gender and occupation queries consistently reflect bias against women. Further, some data has been left out and deemed unimportant. D’Ignazio noted that while producing data requires investment, people don’t always care to know more about such issues as gender-based violence, maternal mortality, evictions, or homelessness. AI systems “don’t just reflect back our own social biases … they are actually reproducing at scale those biases, so they do this kind of extra exponential harm work in the world.”

While it is possible to remember the early days of the Web as full of hope for breaking down hierarchies and promoting democracy and access, Christin observed, those beginnings already revealed gender bias. “There was this metaphor of the digital frontier, which came with settler colonialism and extremely masculinist vibes,” she said. These early choices have matured into a male-dominated Silicon Valley, “an ecosystem that is so concentrated and has made being online so discriminatory for all kinds of marginalized populations.”

Noble has been focused on the gendered dimensions of this tech storytelling, which propagates the idea of smart Silicon Valley engineers who can access funding because the industry is meritocratic. “These stories that we tell about technology, and this cultural framing of tech as embedded with the best and brightest, the great men of science mythologies … certainly dominate in the tech industry,” she said.

Despite the utopian narrative that has been so central to the making of Silicon Valley, Christin said, the vision of a promising digital frontier has taken a dystopian turn. She has been focusing on questions of power: “Not only the distribution of power, but what is the cultural landscape that legitimizes these technologies and the harms they can have.” As a professor working in Silicon Valley, Christin said, critical voices on technology can be hard to find: “the machine kind of carries on.” Even after repeated boom and bust cycles in the tech sector, the current growth of AI has created a concentration of power at a scale rarely seen, suggesting the 19th century industrial revolution. 

Smith addressed attempts by the government to regulate AI. Recently in Colorado, a proposed law would have required companies to test for bias any AI systems making decisions with material impacts in areas such as healthcare, hiring, or housing. When xAI filed a lawsuit claiming that its Grok chatbot would be forced by the bill into promoting the state’s ideological views – even though the bill did not address speech – the Department of Justice joined the suit, and the final bill was watered down substantially. The effort follows from Trump’s “Preventing Woke AI” executive order, in which attempts to mitigate bias were cast as ideological. In this environment, Smith asked, how do we pursue evidence-based accountability?

Christin said, “The question of resistance is so important,” and offered community organizing as a key pathway. She cited a growing distaste for AI among the public and noted recent interest from her students in establishing an AI-critical group. “Creating spaces [for critical discussion] is the only way to push back against the giant tsunami of AI hype we’re all facing right now,” she said. “It’s essential.” 

D’Ignazio stressed the importance of “repoliticizing” the choices and the language of AI leaders, some of whom openly evoke fascist tropes such as “western civilization” and “decadence” and quote figures such as the fascist poet Filippo Marinetti. They are not advocating a return to neutrality, she said, but a violent alternative, “which is a eugenicist agenda, it’s a fascist agenda, it’s a white supremacist agenda, a pro-natalist agenda, it is not a neutral agenda.” The challenge, she said, is to repoliticize and expose these agendas.

As for the possibility of feminist AI, D’Ignazio expressed skepticism: “Under the current political economy of AI, I don’t think feminist AI is possible.” She did offer an alternative vision that would change relationships to governance and the ownership of data and infrastructure, down to the servers and the cloud. In the absence of any meaningful state intervention to rein in big AI companies, she said, smaller experiments have been successful in rethinking these relationships. She described a project at the MIT Data + Feminism Lab in partnership with an activist group researching feminicide in Latin America. 

The panelists shared concerns of inequality at all levels of the AI ecosystem, from funding to a “casual approach” to development to data-level racial and gender bias. The interwoven relationship of government, large corporations, and venture capitalists raises fundamental questions about the current AI boom: is it about the breakthrough of a particular technology or company or global power? Or perhaps the latest boom cycle is about companies in Silicon Valley, and the men who lead them, achieving and cementing their own dominance.

The statement that the first generation of artificial intelligence "did not take gender equality into account at all" highlights how early AI systems were built without safeguards against discrimination, ultimately encoding and amplifying existing societal prejudices.

The primary factors behind this oversight include:

• Biased and Incomplete Training Data. Early AI models were trained on massive historical datasets—such as books, articles, and internet archives—that reflect decades of real-world gender inequality. Because this data was treated as objective truth rather than a flawed record, AI learned to associate men with leadership or technical roles and women with domestic or caregiving positions. Additionally, data specific to women's experiences or health was frequently omitted or deemed unimportant during collection.

• Lack of Diversity Among Creators. The teams designing, coding, and testing early AI systems were overwhelmingly male. Because women were underrepresented in both technical development and decision-making roles, blind spots regarding gender stereotyping and disparate impacts went unnoticed during the creation process.

• Prioritizing Speed and Functionality Over Ethics. The initial push in AI development focused heavily on technological capability, efficiency, and rapid deployment rather than ethical guardrails. As noted by specialists at the Gender Equality Forum in Brussels, massive investments went into building intelligent systems without integrating principles of transparency, safety, or bias mitigation from the start.

• Amplification of Stereotypes. Rather than simply mirroring human bias, unmoderated algorithms actively reinforced it. For example, studies on early language models demonstrated that systems struggled to associate female pronouns with professions like airline pilots or male pronouns with nurses, effectively limiting equal representation in automated outputs


Luzzerty agency, Portugal

Wednesday, November 18, 2026


TECH


OECD updates quality framework for data protection and credibility

The OECD has issued a comprehensive update to its statistical quality framework, setting out how the organization will safeguard the quality, credibility, and reliability of its statistics as the data landscape evolves, it was announced today.

High-quality, internationally comparable statistics and data are essential to effective policy analysis and evidence-informed decision making. The OECD Statistics and Data Quality Assurance Framework provides a coherent and forward-looking approach to safeguarding the quality, credibility and trustworthiness of OECD statistics and data. It updates the OECD’s previous editions to reflect a rapidly evolving data environment, including the growing use of new and secondary data sources, advanced analytical techniques and artificial intelligence. 

The Framework defines how the quality of statistics, data and metadata is understood at the OECD and sets out principles, objectives and processes to support continuous improvement throughout the data lifecycle. While primarily intended to guide quality management across the OECD, it can also serve, alongside the OECD Recommendation on Good Statistical Practice, as a reference for national and international statistical authorities seeking to review, modernise or strengthen their own quality assurance frameworks. By promoting common quality principles and good statistical practices, the Framework aims to reinforce trust in statistics and support their effective use by people and machines.

In a statement released today, the OECD (Organisation for Economic Co-operation and Development) notes that this update comes "as artificial intelligence (AI) and new data sources continue to transform the production, access, and use of statistics."

As artificial intelligence and new sources of data continue to transform how statistics are produced, accessed and used, the OECD has issued a comprehensive update to its statistical quality framework that sets out how the Organisation will safeguard the quality, credibility and trustworthiness of its statistics as the data environment evolves.

The new OECD Statistics and Data Quality Assurance Framework covers the full data lifecycle, from identifying and collecting data through to processing, dissemination and reuse, and is the first edition to explicitly incorporate AI into the assessment and management of statistical quality. As AI systems increasingly mediate access to information, ensuring that reliable statistics can be identified and correctly interpreted is becoming more important.

“Reliable, internationally comparable statistics are the foundation of effective policymaking,” OECD Secretary-General Mathias Cormann said. “As new data sources, analytical methods and artificial intelligence transform how statistics are produced and used, this new Framework will help ensure that OECD statistics remain relevant, credible and trusted.”

The changing data landscape extends well beyond AI. Around 25% of the data currently used to produce OECD statistics come from sources beyond traditional official-statistics transmission programmes, including new sources such as geospatial information, mobile positioning data and commercial transactions. Advances in analytical methods are also changing how these data are processed and used.

AI offers significant opportunities to support statistical production, including by classifying information, detecting anomalies, harmonising metadata and improving access to evidence. At the same time, it creates new challenges for statistical quality. AI-generated or manipulated data may enter the production process, while search engines, large language models and other AI systems increasingly mediate how users find, interpret and reuse statistics, sometimes outside their original context.

The Framework establishes that AI should support, rather than replace, professional statistical judgement. It emphasises human oversight, transparency and traceability, as well as the need to understand where data come from and how they have been transformed.

It also highlights the importance of making authoritative statistics “AI-ready”, with standardised, machine-readable metadata, interoperable formats and clear information on sources and methods helping AI systems identify reliable statistics and interpret them more accurately, while preserving their meaning, context and provenance.

The new OECD Statistics and Data Quality Assurance Framework covers the entire data lifecycle—from identification and collection to processing, dissemination, and reuse—and is the first edition to explicitly incorporate AI into the assessment and management of statistical quality.

"As AI systems increasingly mediate access to information, ensuring that reliable statistics can be identified and correctly interpreted is becoming ever more important," the OECD adds.

OECD Secretary-General Mathias Cormann asserts that "reliable and internationally comparable statistics are the foundation for effective policymaking." "This new Framework will help ensure that OECD statistics remain relevant, credible, and trustworthy as new data sources, analytical methods, and artificial intelligence transform the way statistics are produced and used," states Cormann.

The evolving data landscape extends well beyond AI, the OECD notes, adding that approximately 25% of the data currently used to produce OECD statistics originates from sources outside traditional official statistical reporting programmes—including new sources such as geospatial information, mobile positioning data, and commercial transactions.

The OECD states that advancements in analytical methods are also altering how such data is processed and utilised. It highlights that AI offers significant opportunities to support statistical production, including the classification of information, anomaly detection, metadata harmonisation, and improved access to evidence.

However, the OECD observes that this simultaneously creates new challenges for statistical quality. Data generated or manipulated by AI could enter the production process; meanwhile, search engines, large language models, and other AI systems increasingly shape how users discover, interpret, and reuse statistics—sometimes outside their original context.

The Framework stipulates that AI should support, rather than replace, professional statistical judgement. It emphasises human oversight, transparency, and traceability, as well as the necessity of understanding the origin of data and how it has been transformed.

It also underscores the importance of making reliable statistics "AI-ready"—utilising standardised, machine-readable metadata, interoperable formats, and clear information regarding sources and methods. This helps AI systems identify trustworthy statistics and interpret them more accurately, while preserving their meaning, context, and provenance.

On November 18, 2026, the OECD published an update to its *OECD Statistics and Data Quality Assurance Framework* (53 pages), alongside an announcement titled "As AI transforms the data landscape, OECD strengthens safeguards for trustworthy statistics," aimed at reinforcing the quality, credibility, and trustworthiness of statistics in the face of advancements in artificial intelligence.

Key aspects of the update include:

• Adaptation to AI and new data sources: It updates previous editions to address the growing use of new data sources, secondary sources, advanced analytical techniques, and artificial intelligence.

• Quality and credibility: It establishes a structured approach to maintaining internationally comparable statistics and supporting evidence-based decision-making.

• Implementation and capabilities: It focuses on the practical application of the framework, including the development of skills and tools centered on statistical quality.

• Privacy and data protection: It complements the organization’s broader guidelines on privacy and data protection, which address issues such as trust, cross-border data flows, and privacy-preserving technologies.

mundophone


TECH


Tracking flaws in used building materials facilitates reuse

In circular construction, materials from old buildings are salvaged and reused in other building projects. The European Union this year has proposed legislation that would formalize and expand this concept.

While these reclaimed materials will likely be serviceable, they will not be perfect – and those imperfections can lead to unexpected construction delays and added cost.

Researchers from Cornell Tech and the Cornell Bowers College of Computing and Information Science have developed a documentation tool, Pentimento, that uses video, audio and computer simulation to better match on-site adaptations to the architects’ and engineers’ visions for a project.

The team described their tool in “Building Drift: Documenting On-Site Construction Adaptations Across Material Lifecycles,” which won the Best Paper Award at the Association for Computer Aided Design in Architecture (ACADIA’26), held Oct. 22-24 in Detroit.

With Pentimento, the history of a reclaimed piece of lumber, for example, is documented and stored in a web interface that can be accessed by all relevant parties. This can minimize delays due to unforeseen challenges that result in what’s known as “building drift” – a gradual straying from the structure’s initial vision and design.

“With building drift, what we were trying to explore is, what are the sources of change that happen through that journey of making,” said Ritik Batra, a doctoral candidate in information science at Cornell Tech, and lead author of the paper. “One example is the environment itself, environmental conditions. In the digital world, you can do whatever you want, it’s perfect. But in the real world, it’s not. You need to adjust.”

Co-authors include Thijs Roumen, assistant professor at Cornell Tech and the Cornell Ann S. Bowers College of Computing and Information Science; Steven Jackson, vice provost for academic innovation and professor of information science (Cornell Bowers); and researchers from the Royal Danish Academy’s Centre for Information Technology and Architecture (CITA).

Pentimento leverages both human and computerized input in an attempt to present a complete picture of a material’s history and condition. Five factors contributing to building drift are considered in painting this picture: environmental conditions; constraints due to available materials and tools, particularly if the building site is in a remote location; the hidden history of the materials; the imperfections and limitations of available tools; and knowledge gaps between site owners, designers, builders and other stakeholders.

The European Union is scheduled this year to adopt the Circular Economy Act, which among other things will establish a single market for secondary raw materials and increase the supply of high-quality recycled materials. But while these materials will likely be very good, they will not be perfect.

Pentimento, Batra said, is a way to document and track any flaws or imperfections that could impact future use.

“The challenge is that you have an imperfect reflection of how the materials were used in previous buildings,” Batra said. “What we’re hoping is Pentimento can be used as a low-effort way for construction site people to be able to record what they’re doing, document it, and then everyone down the line can refer to it and get the information they need.’

This work was conducted in the winter and spring of 2026, when Batra was a visiting scholar at CITA. Pentimento was tested on ReShelter, a pavilion built with reclaimed materials near Hvalsø, Denmark, west of Copenhagen. Batra was on site during its construction, and used smart glasses to both capture video and verbally document the construction process.

Video and audio were then uploaded to the Pentimento web interface when Batra returned to the CITA campus and had internet access. The system runs a structure-from-motion script (COLMAP) to estimate camera poses, then generates a 3D Gaussian splat reconstruction that can be overlaid onto the 3D model of the actual structure, resulting in a realistic, shareable 3D scene that can be rendered from any viewpoint within a web browser.

Pentimento’s realistic rendering, the researchers wrote, enables stakeholders to locate and interpret sources of drift relative to the original model.

Roumen said he’s used Gaussian splatting in previous projects focused on machinery – overlaying a CAD model onto the splat to troubleshoot a problem with the machine. But using this technology in architecture is uncharted territory.

“Rather than a machine’s bolt being off,” he said, “now it’s more like the whole world is off. That’s why we were so happy to see people at the conference get excited about how this work, which is already being used in HCI (human-computer interaction), actually makes sense in architecture, too.”

Researchers at Cornell Tech and the Cornell Bowers College of Computing and Information Science developed Pentimento, a documentation tool that uses video, audio, and 3D computer simulation to track imperfections in salvaged construction materials. By creating an accessible digital history of these flaws, the system reduces construction delays, prevents unexpected costs, and makes circular building practices much easier to adopt.

How pentimento works:

• Low-Effort Site Capture. Workers wear smart glasses on the construction site to record video and verbally describe adaptations as they build.

• 3D Reconstruction. The system processes the uploaded footage using structure-from-motion scripts (COLMAP) to generate a 3D Gaussian splat model.

• Digital Overlay. This realistic 3D scene overlays directly onto the architect's original digital blueprint inside a standard web browser. Stakeholders can inspect the exact physical state of the materials from any angle.

Solving "building drift":

Reclaimed materials—such as salvaged lumber—rarely match ideal digital specifications. When builders adjust to real-world imperfections on-site, the final structure gradually strays from the initial architectural design in a process researchers call "building drift".

Pentimento tracks five core factors behind building drift:

• Environmental Conditions. Weather and site environments alter material dimensions and behavior during construction.

• Hidden Material History. Previous uses leave behind unseen wear, nail holes, or structural stresses.

• Material and Tool Constraints. Remote building sites often face limited equipment and supply options.

• Tool Imperfections. Available construction tools have physical limitations that affect precision.

• Stakeholder Knowledge Gaps. Miscommunication often occurs between site owners, designers, and on-site builders.

Real-world testing and broader impact:

• Field Validation. Lead author Ritik Batra tested the system in early 2026 during the construction of ReShelter, a reclaimed-material pavilion near Hvalsø, Denmark.

• Policy Alignment. The tool supports growing regulatory pushes for sustainability, such as the European Union's Circular Economy Act, which aims to establish a unified market for secondary raw materials.


mundophone


Tuesday, November 17, 2026


TECH


Russia-linked hackers spied on NATO and EU emails

Hackers with ties to Russia infiltrated servers to spy on emails from NATO and the European Union. Researchers at the cybersecurity firm ESET uncovered a cyber-espionage operation that compromised email servers belonging to government organizations in Romania and Kazakhstan.

The campaign has been attributed with high confidence to the group Turla, known for its links to Russian intelligence services.

The attackers employed a previously unknown suite of malicious tools, dubbed "Cereal," to search for and collect messages related to NATO and European Union institutions.

Hackers linked to Russia’s FSB quietly compromised a Romanian government organization’s servers to collect emails related to NATO and the EU in December 2025, a Slovak cybersecurity firm has revealed. 

Using an advanced suite of tools that the researchers dubbed Cereal, a pun on the technology of serialization, emails going through Romanian government servers were scanned for a relation to NATO and the European Union. If this was discovered, the malicious software would create a copy for its Russian spymasters. 

In particular, one component, CerealBox, targeted messages involving NATO and EU institutional addresses, the cybersecurity form ESET said. The module selected emails with Word or PDF attachments using predefined filters, then compressed and encrypted copies for later retrieval by the attackers.

The hack was discovered by the Bratislava-based  company and made public on Nov. 10. ESET had first discovered the tool being used against Kazakhstan in November 2025, and found the infiltration of Romania’s Microsoft Exchange servers a month later. 

In a blog post and press release, the company attributed the attack to the known hacking group Turla, which it said was generally considered to be affiliated with Russia’s FSB, the country’s domestic intelligence agency. Turla has also been involved in attacks against high-profile Ukrainian targets, and the researchers said 70% of countries the group targeted were post-Soviet or post-communist states in Eastern Europe and Central Asia. The APT – a term designating an “Advanced Persistent Threat,” or known hacking group – primarily attacks government institutions.

According to ESET’s investigation, the operation utilized malicious components developed specifically for Microsoft Exchange servers. Rather than indiscriminately searching through all available files, the system was designed to examine email messages and identify content that met specific criteria.

One of the components, named "CerealBox," searched for messages associated with institutional email addresses belonging to NATO and the European Union.

The system was also capable of selecting emails that contained attached Word documents or PDF files.

Messages deemed relevant were copied, compressed, and encrypted for later retrieval.

This approach allowed the attackers to focus their operation on information with potential strategic value.

One of the most concerning features involved how the tools communicated.

Many malicious programs rely on external servers to receive instructions or transmit stolen data.

"Cereal," however, used the compromised Exchange servers themselves as part of the operation's infrastructure.

This technique made it more difficult to detect suspicious communications and minimized the presence of malicious files within the system.

According to ESET, the tools were designed to execute certain components directly in memory, allowing them to remain covert for extended periods.

This combination of methods demonstrates a high level of technical expertise regarding the internal workings of Microsoft Exchange. The investigation identified the use of "Cereal" against a government organization in Kazakhstan in November 2025.

Subsequently, ESET uncovered a similar operation targeting Romanian government servers.

The intrusion in Romania was determined to have taken place on December 23, 2025.

The investigation was made public on November 10, 2026.

These details are significant for understanding the timeline: while the public disclosure is recent, the identified attacks date back to the previous year.

Attribution to the Turla group is based on technical analysis of the tools, comparisons with past operations, and links to other known malicious components.

Despite the high level of confidence expressed by the researchers, the attribution of cyber operations remains based on technical evidence and does not constitute a legal judgment regarding the individuals responsible.

Romania is a member of both NATO and the European Union, occupying a geographically significant position for the security of Europe’s eastern flank.

The collection of institutional communications could potentially reveal diplomatic stances, relationships between entities, and other sensitive information.

However, the investigation does not confirm that all emails related to NATO or the European Union were compromised.

Furthermore, it cannot be concluded that the internal systems of these organizations were directly breached.

Above all, the operation highlights the espionage risks associated with email servers used by public institutions.

For organizations that use Exchange, this case underscores the importance of keeping systems up to date, controlling administrative access, and monitoring for anomalous behavior—even when traffic appears to remain within the established infrastructure.

Researchers at cybersecurity firm ESET revealed that the Russia-linked hacking group Turla—widely assessed to be affiliated with Russia's FSB—used a stealthy toolkit called Cereal to monitor emails tied to NATO and the European Union on a compromised government server in Romania.

Key details:

• Timeline & Discovery: ESET published its findings on November 10, 2026. Researchers first spotted the Cereal toolkit on a government email server in Kazakhstan in November 2025, and identified it on a Romanian government organization's Microsoft Exchange server in December 2025.

• Targeting & Malware Mechanics: A component named CerealBox scanned email traffic for messages with Word (DOC/DOCX) or PDF attachments matching hard-coded filters. On the Romanian server, it was configured to target correspondence involving NATO and EU institutional addresses, compressing and encrypting matching messages for exfiltration.

• Stealth & Command Control: Rather than relying on external command-and-control (C2) servers, the toolkit co-opted compromised Exchange servers for C2 and executed payloads in memory via components such as CerealRunner and CerealNeuron to minimize its footprint.

• Official Response: Romania's intelligence service confirmed the intrusion by Turla, noted cooperation with EU and NATO partners, and stated that the breach was contained without sensitive data being extracted. On November 17, 2026, Russia denied allegations of cyber espionage against the Romanian government.

mundophone


TECH


Learning reveals hidden information about network structure

Learning in the brain involves changes in the connections between neurons, but its effects show up in the system’s overall behavior. How do the many changes in these connections combine to alter the system’s function? In a new study, Technion researchers examined this relationship using mathematical models of neural networks, showing that a network’s function and learning reveal different aspects of its internal structure.The paper by Prof. Omri Barak and research student Yoav Ger of the Technion’s Ruth and Bruce Rappaport Faculty of Medicine was selected for an oral presentation at NeurIPS 2026, one of the world’s leading conferences in artificial intelligence and computational neuroscience. Of the 30,709 papers submitted to the conference, only 112 (approximately 0.36%) were selected for oral presentations.

The researchers focused on a particular type of recurrent neural network, used to model how the brain processes information. They developed a mathematical description that makes it possible to calculate how a network changes during learning using a small number of variables. Their analysis distinguished between two types of properties: those that determine the network’s actual behavior and those that do not affect its current performance but influence how it learns in the future. These “hidden” properties are not apparent when examining the system’s behavior alone, but they may emerge when the system is required to learn a new task.

In one example in the study, two networks with different internal structures responded identically to the same inputs. However, when trained under the same conditions, they followed different learning trajectories: one experienced a period in which improvement slowed considerably, while the other improved more steadily. Learning itself can therefore serve as a research tool, revealing differences that are not apparent when examining only the system’s current function.

The study also demonstrated that, under certain conditions, these hidden properties can retain traces of the network’s learning history. Networks initially trained on different tasks and subsequently trained on a shared task achieved similar performance, yet their hidden structural properties still made it possible to identify each network’s training history.

“The question of how changes in the structure of a complex system affect its behavior arises in many fields of science,” said Prof. Barak. “In the networks we studied, we found that understanding what the system does today is not enough to describe how it will learn in the future. The way it changes through learning can reveal structural differences that remain hidden in its current function.”

The results were obtained using mathematical models and computer simulations. They suggest a direction for experiments in biological systems: examining how systems with similar behavior change in response to the same learning process, and determining which internal differences can be revealed in this way.

The research was supported by the Israel Science Foundation (ISF) and the Human Frontier Science Program.

Unveiling the hidden layers of deep learning...In a Scientific American article entitled “Springtime for AI: The Rise of Deep Learning,” computer scientist Yoshua Bengio explains why complex neural networks are the key to true artificial intelligence as people have long envisioned it. It seems logical that the way to make computers as smart as humans is to program them to behave like human brains. However, given how little we know of how the brain functions, this task seems more than a little daunting. So how does deep learning work?

Evidently, these so-called “hidden layers” play a key role in breaking down visual components to decode the image as a whole. And we know there is an order to how the layers act: from input to output, each layer handles increasingly complex information. But beyond that, the hidden layers—as their name suggests—are shrouded in mystery. 

As part of a recent collaborative project called Tensor Flow, Daniel Smilkov and Shan Carter created a neural network playground, which aims to demystify the hidden layers by allowing users to interact and experiment with them. 

There is a lot going on in this visualization, and I was recently fortunate enough to hear Fernanda Viégas and Martin Wattenberg break some of it down in their keynote talk at OpenVisConf. (Fernanda and Martin were part of the team behind Tensor Flow, which is a much more complex, open-source tool for using neural networks in real-world applications.)

Rather than something as complicated as faces, the neural network playground uses blue and orange points scattered within a field to “teach” the machine how to find and echo patterns. The user can select different dot-arrangements of varying degrees of complexity, and manipulate the learning system by adding new hidden layers, as well as new neurons within each layer. Then, each time the user hits the “play” button, she can watch as the background color gradient shifts to approximate the arrangement of blue and orange dots. As the pattern becomes more complex, additional neurons and layers help the machine to complete the task more successfully.

Besides the neuron layers, the machine has other meaningful features, such as the connections among the neurons. The connections appear as either blue or orange lines, blue being positive—that is, the output for each neuron is the same as its content—and orange being negative—meaning the output is the opposite of each neuron’s values. Additionally, the thickness and opacity of the connection lines indicate the confidence of the prediction each neuron is making, much like the connections in our brains strengthen as we advance through a learning process.

Interestingly, as we get better at building neural networks for machines, we may end up revealing new information about how our own brains work. Visualizing and playing with the hidden layers seems like a great way to facilitate this process while also making the concept of deep learning accessible to a wider audience.

“Learning Reveals Hidden Information About Network Structure” is a 2026 study by researchers at the Technion – Israel Institute of Technology demonstrating that how a neural network learns can expose internal structural differences that remain invisible when observing its current behavior alone. Authored by Prof. Omri Barak and Yoav Ger, the paper was selected for an oral presentation at NeurIPS 2026, ranking among the top 112 submissions out of 30,709.

Core findings & methodology:
Using mathematical models and computer simulations of recurrent neural networks (RNNs), the researchers derived a low-dimensional mathematical framework to track how internal connections evolve during training.
• Behavioral vs. Hidden Properties. The mathematical analysis separates network parameters into two distinct categories. Behavioral properties dictate the system's current input-output performance, while hidden properties have no effect on present behavior but govern how the network adapts to future tasks.
• Divergent Learning Trajectories. Two networks with different internal structures can produce identical outputs for the same inputs. When trained on a new task under identical conditions, their hidden properties cause them to follow different learning paths, such as one network hitting a temporary plateau while the other improves steadily.
• Traces of Learning History. Hidden structural properties can preserve a record of past training. Even when networks initially trained on different tasks are later retrained on the exact same task and reach identical performance levels, their hidden variables still reveal their prior training histories.

Scientific implications:
• Learning as a Diagnostic Tool. Observing how a system changes during training serves as an experimental probe to uncover internal differences that static functional testing misses.
• Applications to Biological Neuroscience. The findings offer a framework for designing biological experiments. Researchers can compare brains or biological circuits that exhibit identical baseline behaviors by measuring how they diverge when subjected to the same learning paradigm.

mundophone

Monday, November 16, 2026


PURISM


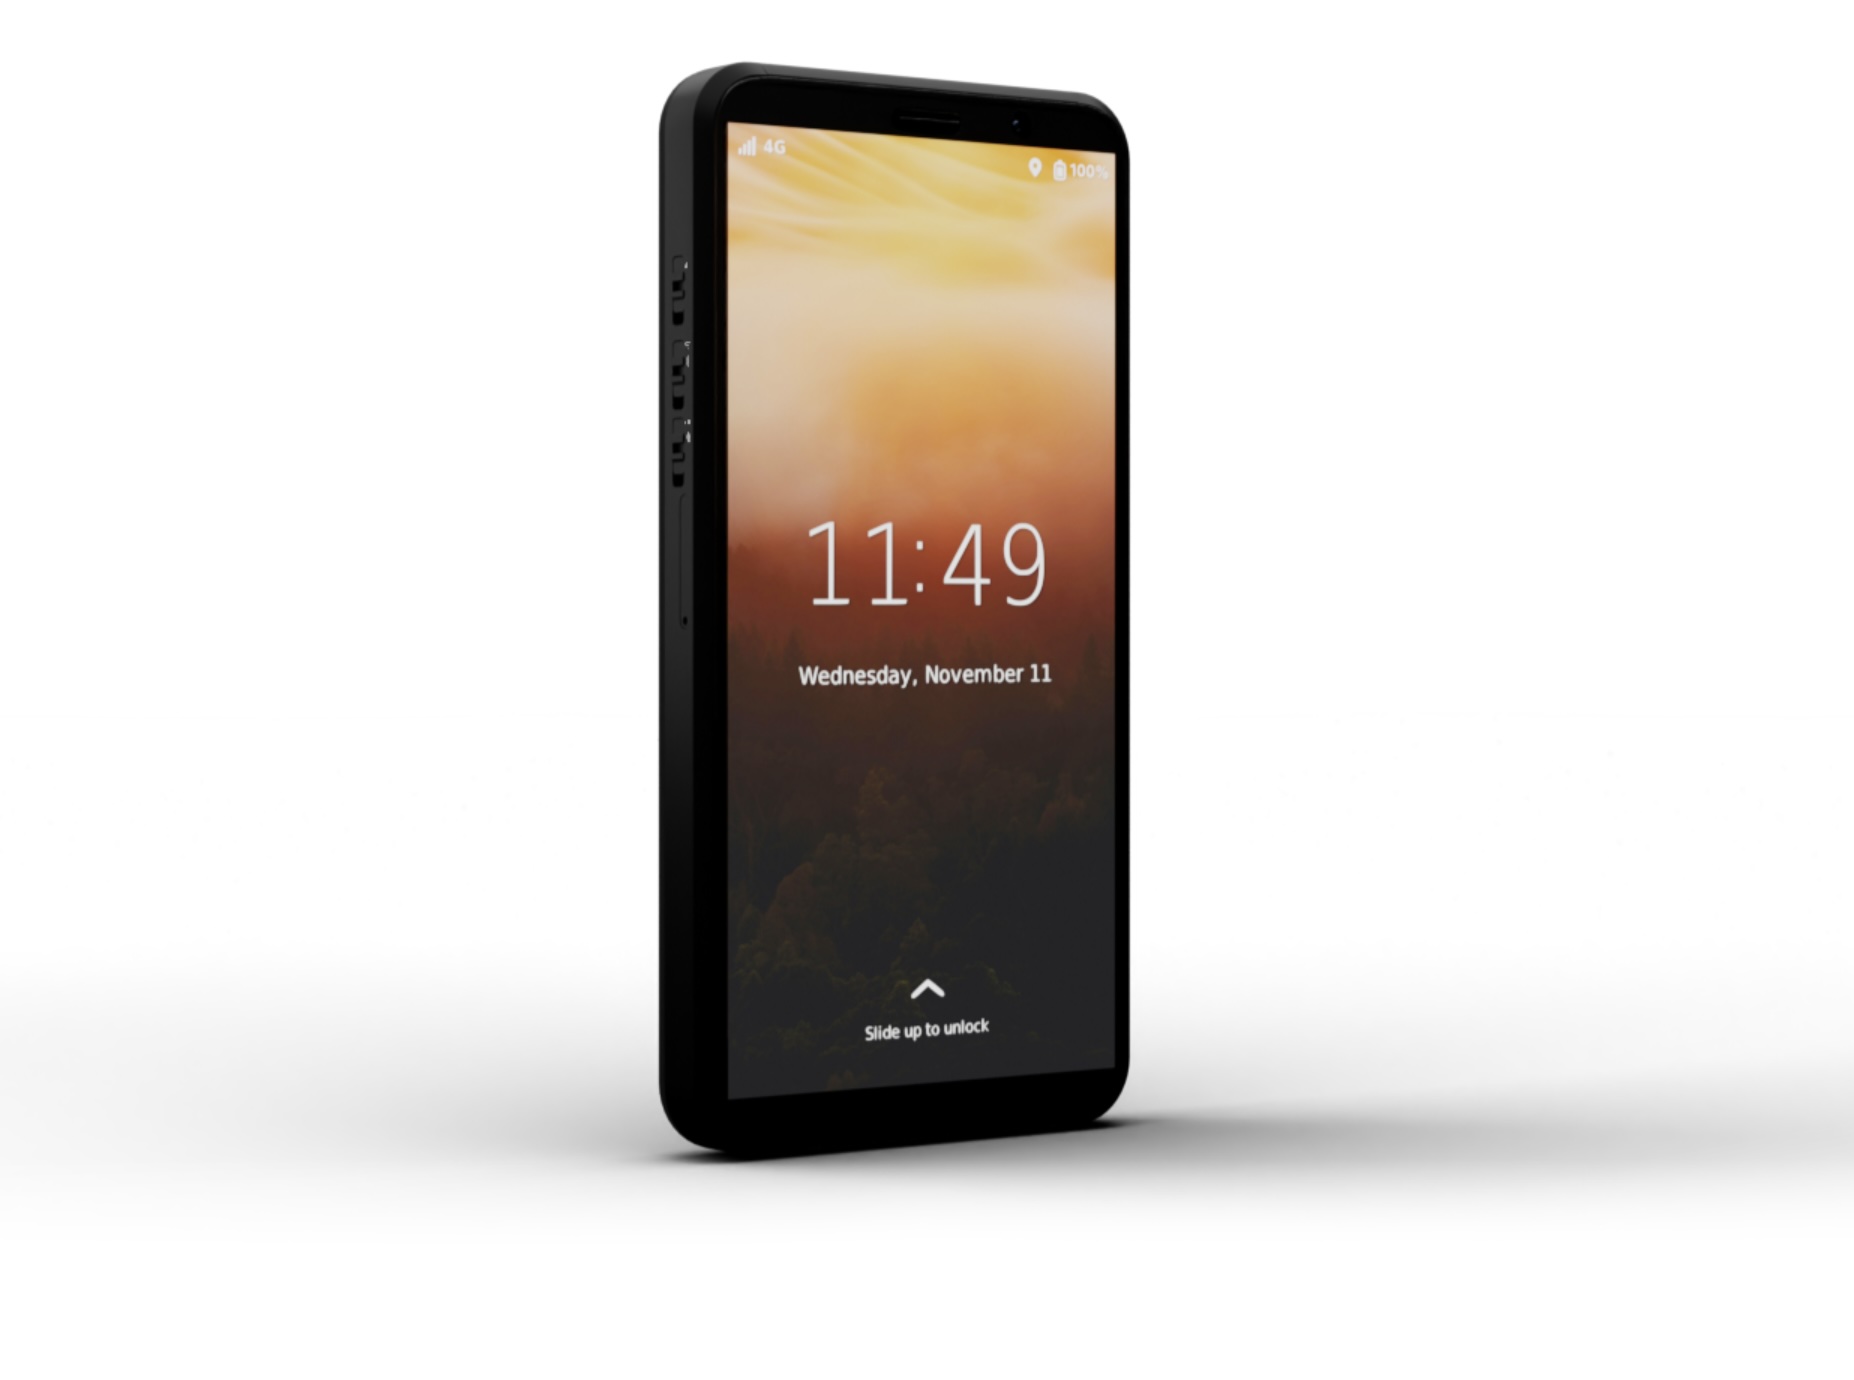
Linux smartphone with 8-core RISC-V chip and 8 GB RAM goes official with hefty price tag

Purism has announced the Librem 5 v2, a follow-up to its privacy-focused Linux phone, and the headline change is the processor. The original Librem 5 ran a quad-core NXP i.MX 8 ARM chip; the v2 moves to the SpacemiT K1, an eight-core RISC-V SoC. Purism is funding it the same way it funded the first one, through a rolling crowdfunding campaign on its own site that opens to the public on November 17 and runs until February 15, 2027.

Purism is a brand that is well-known for their open-source hardware efforts. The Librem 5 smartphone was launched all the way back in 2019, and was powered by an 1.5 GHz quad-core ARM CPU paired with 3 GB of RAM and 32 GB of storage.

However, for the Librem 5's successor, which the company has dubbed the Librem 5 v2, a massive architectural change is being planned. To be precise, the smartphone will now go for a RISC-V chip instead of an ARM one.

But make no mistake - the SpacemiT K1 is not going to take on the Snapdragons and Dimensity-s of the world anytime soon in terms of raw performance. The amount of compute on offer is very humble, and only sufficient for basic day-to-day tasks. After all, that's all what a no-nonsense smartphone really needs, to be honest.

The original Librem 5, a 5.7" smartphone running the company's in-house Linux-based PureOS — which, the company is at pains to point out, does not follow the herd in using Google's Android Open-Source Project (AOSP) as its base — on an NXP i.MX 8M quad-core Arm Cortex-A53 system-on-chip. Its successor retains the same overall design, with the same 720×1,440-resolution display, but moves to the SpacemIT K1.

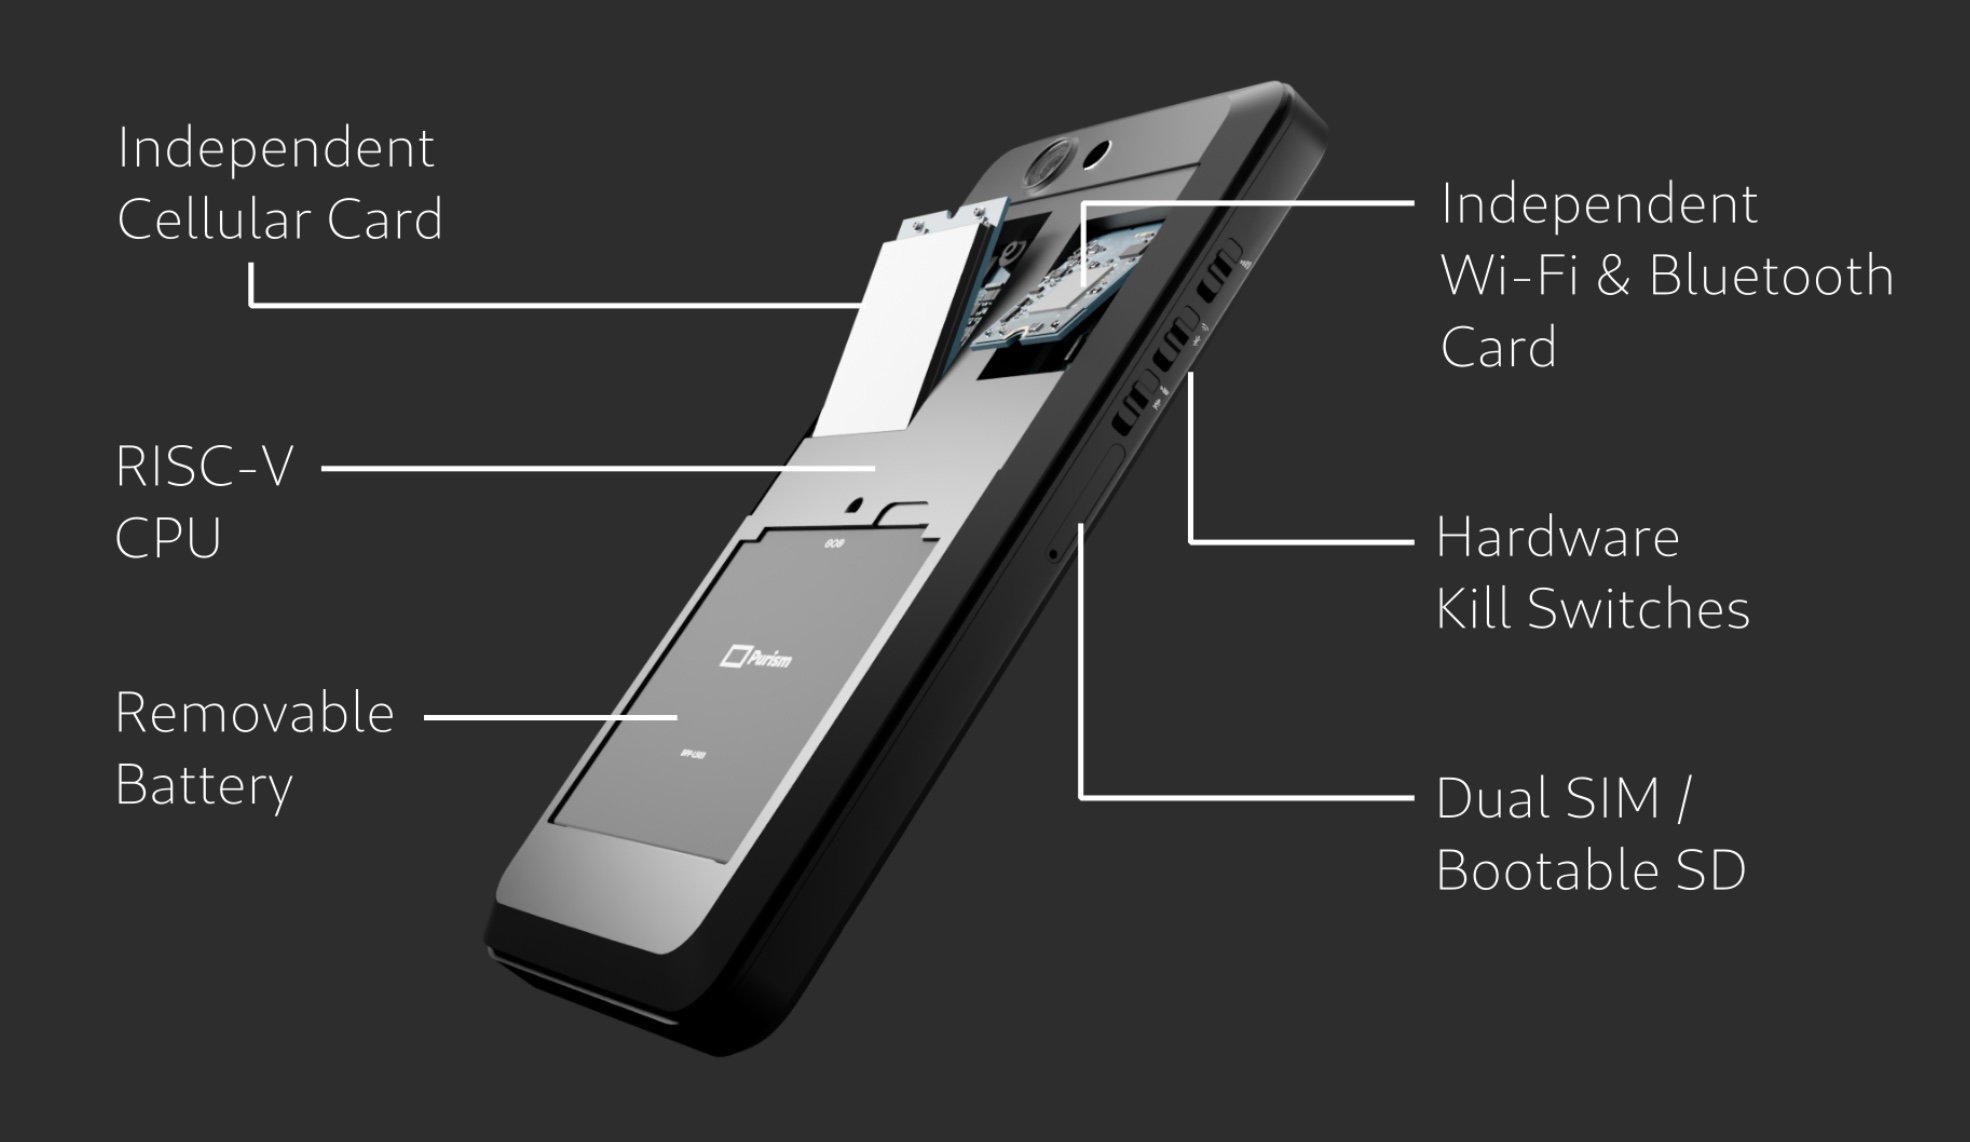
It's a big move: not only does the K1 boast twice as many processing cores but it's based on an entirely different architecture. Where the i.MX 8M is built on the proprietary Arm architecture, the SpacemiT K1 uses the free and open source RISC-V architecture — though SpacemiT's particular implementation is proprietary, as with NXP's Arm chip. At the same time, the phone gets more than twice the RAM, going from 3GB to 8GB, and four times the internal storage, going from 32GB to 128GB expandable via microSD.

The shift hasn't changed the company's privacy focus, though. The redesigned phone still includes hardware "kill-switches" for the microphone, camera, cellular, and combination Wi-Fi and Bluetooth radio modules, while the radios themselves are on user-removable modules to turn the phone into a small-scale airgapped tablet. The 4,500mAh battery is removable and user-replaceable, there's a 3.5mm analog audio jack, dual-SIM support, and support for using an external display via the USB Type-C port which is also used for charging. There's even a smartcard slot.

The smartphone will feature a 5.7-inch display with a resolution of 720 x 1440, which is the same as before, color reproduction or brightness performance details have not been shared. Other notable features include 13 MP and 8 MP rear and front cameras, a 4500-mAh removable battery, dual SIM and SD card support, a 3.5-mm audio jack, hardware kill switches, SD boot support, and a Type-C port.

According to Purism, the Librem 5 v2 should run cooler, faster, and have longer battery life. Of course, the Linux-based smartphone will continue running PureOS. The product is ready for launch on the 17th of November, and the funding phase will continue till 15th February, 2027.

The rest of the spec sheet reads like a list of everything owners complained about on v1. Memory goes from 3 GB to 8 GB, storage is 128 GB, and the microSD slot jumps from roughly 10-14 MB/s to 80 MB/s, quick enough that Purism says you can boot an OS from the card. The 5.7-inch 720 x 1440 display carries over, as does the removable battery, now rated at 4,500 mAh. The cameras are 13 MP at the rear and 8 MP at the front, backed by hardware video encoding.

Purism’s three hardware kill switches remain, physically cutting power to the cellular modem, to Wi-Fi/Bluetooth, and to the microphone and cameras. The cellular and Wi-Fi modules are still replaceable. The modem is an improved 4G part, with 5G listed only as a future module. There is also a smart card slot, a 3.5 mm jack, and USB-C with display output. Purism’s spec table says dual SIM, although LinuxGizmos reports the company is still evaluating how the second SIM will be implemented, so treat that one as provisional.

Software is PureOS, Purism’s Debian-based distribution. Android apps are handled through Waydroid, where they cooperate.

Why RISC-V, and why it is a gamble...The appeal for Purism is easy to see. RISC-V is an open instruction set, which suits a company whose whole pitch is controlling every layer of the stack. Purism also argues the first phone was held back by heat more than by compute, writing that “performance on the Librem 5 is often limited by thermals, not CPU power.” It claims the new board runs cooler and faster and lasts longer per charge. Those are claims, not measurements, and there is no hardware to test yet.

The company is unusually candid about the software, too. Its campaign page admits that “RISC-V is not yet drop-in and boot-up ready for PureOS.” Mainline Linux support for the K1 has been moving along, but a phone needs far more than a kernel that boots. Modem integration, power management, GPU acceleration and a camera pipeline all have to land before this is a daily driver, and that is what the next year and a half is for.

The price and the wait...The phone costs $1,599 with no service bundled, or $129 down followed by fifteen monthly payments of $99. Early backers get extras rather than discounts, such as a Founders Edition and an accessories pack for the first 100 public orders. The campaign’s goal is 2,500 orders, and a 5,000-order stretch goal would move electronics manufacturing to Purism’s own facilities in the US.

Timing is the hard part. Purism’s FAQ puts the dev kit six to seven months after the campaign closes and the phone 14 to 15 months after, which lands around May 2028, with a beta for backers in Q4 2027. The campaign page also says plainly that rewards are not guaranteed and that there are no refunds. Anyone who waited for the first Librem 5, announced in 2017 and first shipped in 2019, will weigh that carefully. For everyone else, it is one of the more serious attempts yet to put a full-size Linux phone on an open ISA, and the interesting question is whether the software catches up before the hardware ships.


by mundophone


TECH


Hydropower study reveals energy potential in Appalachia

Small hydropower systems could generate 22.6 megawatts of electricity in a remote part of western North Carolina, enough to power 5,000 homes in an area where the rugged, heavily forested terrain limits reliable access to energy, according to a recent study.

Researchers from the U.S. Department of Energy's (DOE) Oak Ridge National Laboratory (ORNL) collaborated with the Eastern Band of Cherokee Indians (EBCI) to survey the Tribe's lands, known as the Qualla Boundary, and determine whether micro-hydropower technologies could be a viable source of electricity for communities in remote pockets of the 83-square-mile (215-square-kilometer) tract. Micro-hydropower systems generate up to 100 kilowatts (kW) of energy by harnessing the natural flow of streams.

ORNL scientists and the Tribe used a combination of fieldwork, hydrological modeling, data mining, machine learning, remote sensing and high-resolution satellite imagery to stitch together a finely detailed 3D map of the Qualla Boundary landscape. Using this as a guide, the team assessed the hydropower potential of more than 1,500 separate sites.

The findings demonstrate how advanced modeling and emerging energy technologies could strengthen energy resilience in the region on a broader scale.

"The Qualla Boundary is a microcosm of Southern Appalachia," said Evin Carter, an ecologist and principal investigator at ORNL. "It captures the full range of conditions found across the region, from high-elevation, heavily forested mountain landscapes to lower-elevation community centers and developed areas. This allowed us to evaluate micro-hydropower across the full spectrum of settings where it could be deployed in Appalachia and, potentially, other mountain rural regions."

The study also indicates that the placement of micro-hydropower devices at strategic sites within the Qualla Boundary could simultaneously generate power and improve aquatic habitats for fish and other wildlife in the area, which Carter described as a world biodiversity hotspot. With local economies and livelihoods dependent on these rivers, the researchers focused on areas that could meet the twin goals of reliable power and river stewardship, increasing the likelihood of implementation and community support.

ORNL researchers are exploring the technical potential of "hidden hydro," in which emerging technologies can be used to tap into new sources of hydropower and contribute to a more secure, affordable and reliable energy supply.

Mountain communities face energy access challenges...The EBCI Tribe has about 15,000 members, and their community is located on a particularly craggy stretch of the Blue Ridge Mountain Range. A portion of the Qualla Boundary's population is dispersed into areas where the ground is too uneven and steep to easily accommodate the installation of conventional electrical infrastructure. Like other residents in rural Appalachia, some households in these remote spots may depend on diesel generators for electricity for extended periods due to severe weather or other grid impacts. Outages are frequent and long, even where electrical infrastructure does exist, because conditions make it difficult to maintain connectivity.

The EBCI has long sought to improve its members' access to electricity. Though the Qualla Boundary is home to the Oconaluftee River basin—which has many fast-moving, well-fed waterways that could be harnessed to make energy—the Tribe has been reluctant to invest in conventional hydropower dams. The Tribe did not want to further segment its river system and possibly impede the movement of fish and other aquatic life.

Bunches Creek flows through the Indian Creek Campground in the Qualla Boundary. This higher-elevation stream is one of several sites that ORNL and the Eastern Band of Cherokee Indians are considering for a potential micro-hydropower installation to improve fish passage and local energy access. Credit: Genevieve Martin, ORNL/U.S. Department of Energy

"This project is assisting in assessing our full range of options to harness the energy available in natural Earth systems and contribute to long-term environmental and economic sustainability," said Mike LaVoie, director of EBCI Natural Resources.

Why micro-hydropower might make sense.The investigation into micro-hydro as a possible solution grew from discussions between the Tribe's Natural Resources Department and Carter in his capacity as the executive director of the Southern Appalachian Biosphere Cooperative, of which the EBCI is a member.

Carter has the skill set and professional background that make him uniquely suited to take on this question. As an ORNL ecologist, he has focused his research on Appalachia for more than a decade, developing a deep knowledge of the region's natural environment and fauna. He is an expert at using multiple sources of data to model, map and categorize large chunks of landscape with granular precision. Carter also brings the strength of ORNL's Water Power Program, which develops, evaluates and deploys new hydropower technologies.

One such technology is micro-hydropower. Carter and the EBCI considered two types of this technology: stand-alone micro-turbines and vortex generators. Vortex generators can produce up to 100 kW and are well suited for community-scale applications, such as clusters of homes or larger facilities like health centers or office buildings. Micro-turbines generally produce more than 1 kW and are better suited to powering individual homes and small businesses. Both technologies are commercially available with water intake mechanisms designed to keep fish out of the turbines.

Carter and the EBCI researchers hypothesized that micro-hydro installations could be most productively deployed at locations where fish movement was most impeded by barriers. In this case, a "barrier" could be as big as a conventional hydropower installation, like the Ela Dam, or as simple as a culvert at a road crossing.

If the barrier was removed and replaced by a damless micro-hydro installation, the EBCI could achieve its two goals at once: more reliable, affordable energy and a more connected river system that supports fish and wildlife, recreation and local economies.

To test the theory, the team chose brook trout as a proxy species for its inquiry. Their widespread presence throughout the Oconaluftee basin, from the bottomlands to the highest mountain streams, defined the boundaries of the study area.

Next, the team identified 1,533 potential barriers to fish movement in the study area using available data sets and light detection and ranging, or LiDAR, imagery from the U.S. Geological Survey. Using hydrological modeling, researchers estimated the hydropower potential and aquatic restoration gains if those barriers were removed.

About 533 locations showed potential as possible micro-hydro sites. The study identified 366 sites capable of producing at least 2 kW, which is enough to support single-home micro-turbine systems, the most common development scenario.

The study also found several sites above 3,900 feet (1,190 meters) in elevation that could produce more than 100 kW of hydropower generation, which exceeds the usual definition of micro-hydropower. These results are promising for remote Appalachian communities, as the Qualla Boundary reflects the region's diversity in terrain, land use, economic status and energy access. This suggests that similar communities across Appalachia may benefit from micro-hydro development.

Researchers will now conduct field assessments at the most promising sites to refine generation estimates and identify locations for pilot demonstration projects. The Tribe and researchers will also conduct field surveys of brook trout to further guide restoration efforts.

Appalachia has vast energy potential because of its rich underground fossil fuel deposits, strong renewable resources like wind and micro-hydropower, and emerging investments in clean and nuclear tech.

Fossil fuel reserves:

• Natural Gas: The region sits atop major formations like the Marcellus Shale (spanning Pennsylvania, West Virginia, and Ohio), which produces a massive share of the nation's natural gas supply.

• Coal: For over a century, the Appalachian Plateau has been a primary source of American coal due to its ancient exhumed sedimentary basins and thick rock layers that trapped organic plant material.

• Petrochemicals: Low-cost natural gas has driven the development of regional manufacturing and petrochemical plants, as highlighted by the U.S. Department of Energy.

Renewable energy potential:

• Solar and Wind: Rural and hilly landscapes across states like Kentucky and West Virginia provide ample open land and wind resources to replace or offset declining coal operations.

• Micro-Hydropower ("Hidden Hydro"): Mountain rivers and high-elevation streams offer significant potential for small-scale, river-friendly hydroelectric generation, as studied by researchers at Oak Ridge National Laboratory.

Emerging technologies:

• Advanced Nuclear Power: Programs like "Atoms for Appalachia" are evaluating how states like West Virginia, Virginia, and Kentucky can use small modular and advanced nuclear reactors to power industrial growth and create new jobs


Provided by Oak Ridge National Laboratory 

DIGITAL LIFE Why the first ai "did not take gender equality into account at all"... The first wave of artificial intelligence (AI)...